
Install
Inside DeepSeek Harness, with dsh-market
dsh plugin --profile web add dshmarket
Or from the command line
dsh plugin --profile web add @neptune810/dsh-model-router
Installing runs third-party code with your own permissions — it can read your files, use your credentials and reach the network. Review the source first, and pin a commit (github:owner/repo#sha) when you can.
README
English | 中文
A DeepSeek Harness plugin that keeps a pool of models and routes every step to one of them with its reasoning effort set. Thinking stays on — DeepSeek rejects a thinking-enabled request whose history contains a tool call made with thinking off.
Routing table
| Step class | Decided by | Reasoning effort | Internal point |
|---|---|---|---|
trivial |
a clearly cheap intent (translate, rename, reformat) in a short step | low |
~50 |
standard |
a plain short request with no engineering cue | low |
~50 |
engineering |
engineering cues, code/diff/XML structure, or an agent tool loop | high |
~75 |
hard |
a dense engineering brief, or failures earned inside the task | high (max when allowMax) |
~75 / 100 |
high is the default ceiling. V4.1-Flash drives effort from an internal 1–100 scalar and exposes
three preset names; high corresponds to roughly 75, which is where the published effort curve is
still steep. Pushing past it costs about 1.6–1.8x the output tokens for a marginal gain.
Authorization scopes, the model pool and task presets (v0.5)
control decides what the router owns, and a manual pick only counts in the scope that owns it: an
effort change stands down full/effort but not model, and a model switch stands down
full/model but not effort. While the router is down it stays out until the next command or the
composer control's resume action.
| Scope | Owns |
|---|---|
full — 模型+思考 / Model+Effort |
model + reasoning effort |
effort — 思考 / Effort |
one model you pick in the panel: the router only sets that model's thinking level |
model — 模型 / Model |
model only; the session keeps its thinking level |
In effort scope the panel first asks you to pick exactly one model
(POST /model-router/effort-model, reported by /state as effortModel / effectiveEffortModel).
Until you do, the router stays out entirely — it changes neither the model nor the effort. Once one is
bound, a manual model switch does not stand it down; changing the thinking level by hand does.
The client half registers its control into the shipped conversation.input.model seat at priority -1,
taking over the composer model cell; it carries the official model + effort sections plus the scope
switch, the resume action, the task-type picker, the model pool and the task presets, and talks to the
host over same-origin /model-router/* routes.
Model pool. Only pooled models are ever selected.
pool:
  - { id: deepseek-official/deepseek-flash, cost: 1, tier: cheap }
  - { id: deepseek-official/deepseek-v4-pro, cost: 8, tier: strong, maxPerTask: 3 }
  - { id: deepseek-official/deepseek-v4-flash-vision-exp, cost: 1, tags: [vision] }
  - { id: vendor-x/writer-pro, cost: 20, weights: { 小说续写: 95 } }
tier: strong is what hard steps and evidence escalation prefer; cost feeds
scoring.costPenalty; maxPerTask caps how many steps of one task may spend that entry; a
vision tag is required for image steps once any pooled model carries one.
Task presets. A user-defined task type with rules and per-model weights:
presets:
  小说续写:
    match: ["续写", "小说", "文风", "/chapter\\s+\\d+/i"]
    weights: { "vendor-x/writer-pro": 95, "deepseek-official/deepseek-v4-pro": 60 }
  代码重构:
    match: ["重构", "refactor", "架构"]
    weights: { "deepseek-official/deepseek-v4-pro": 90 }
A type pinned in the composer always wins; with nothing pinned the keyword rules run
(classifier: rules). Third-party models keep their own effort vocabulary: the router asks the
provider what it supports, picks the nearest level, and sends no effort field when the model
advertises none.
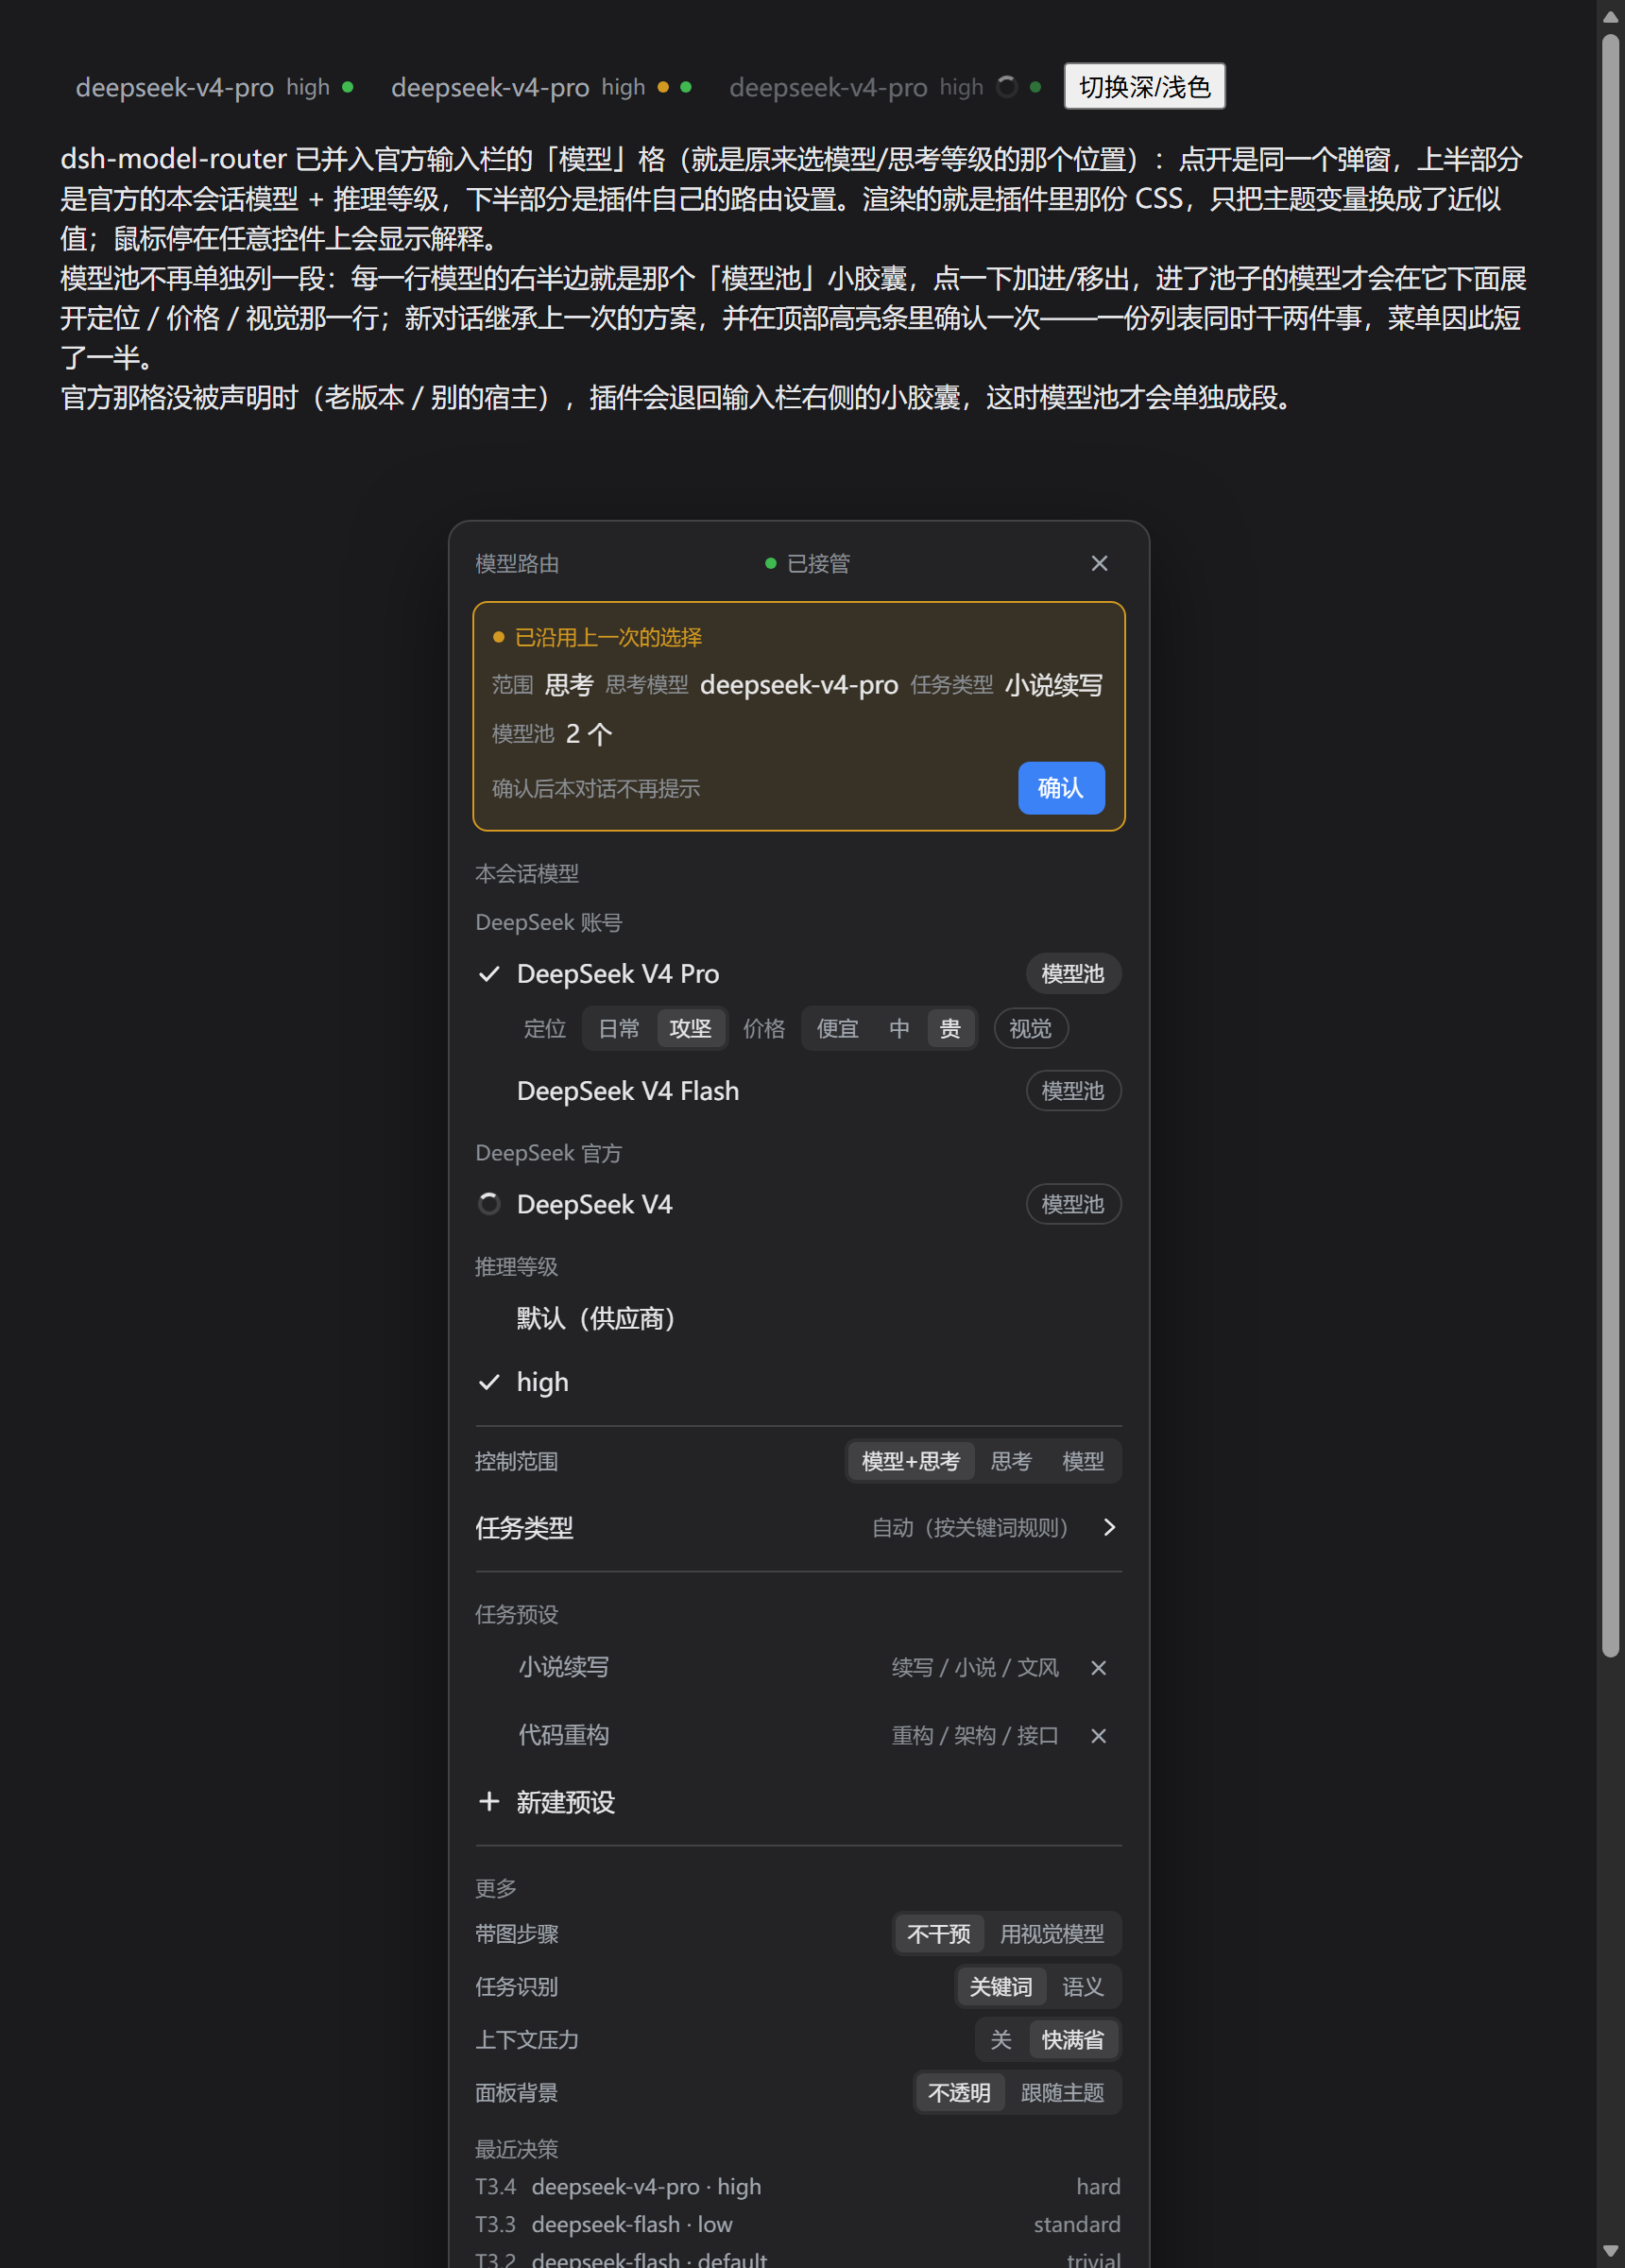
Opaque by default (the theme menu colour is translucent, which let the conversation
show through): 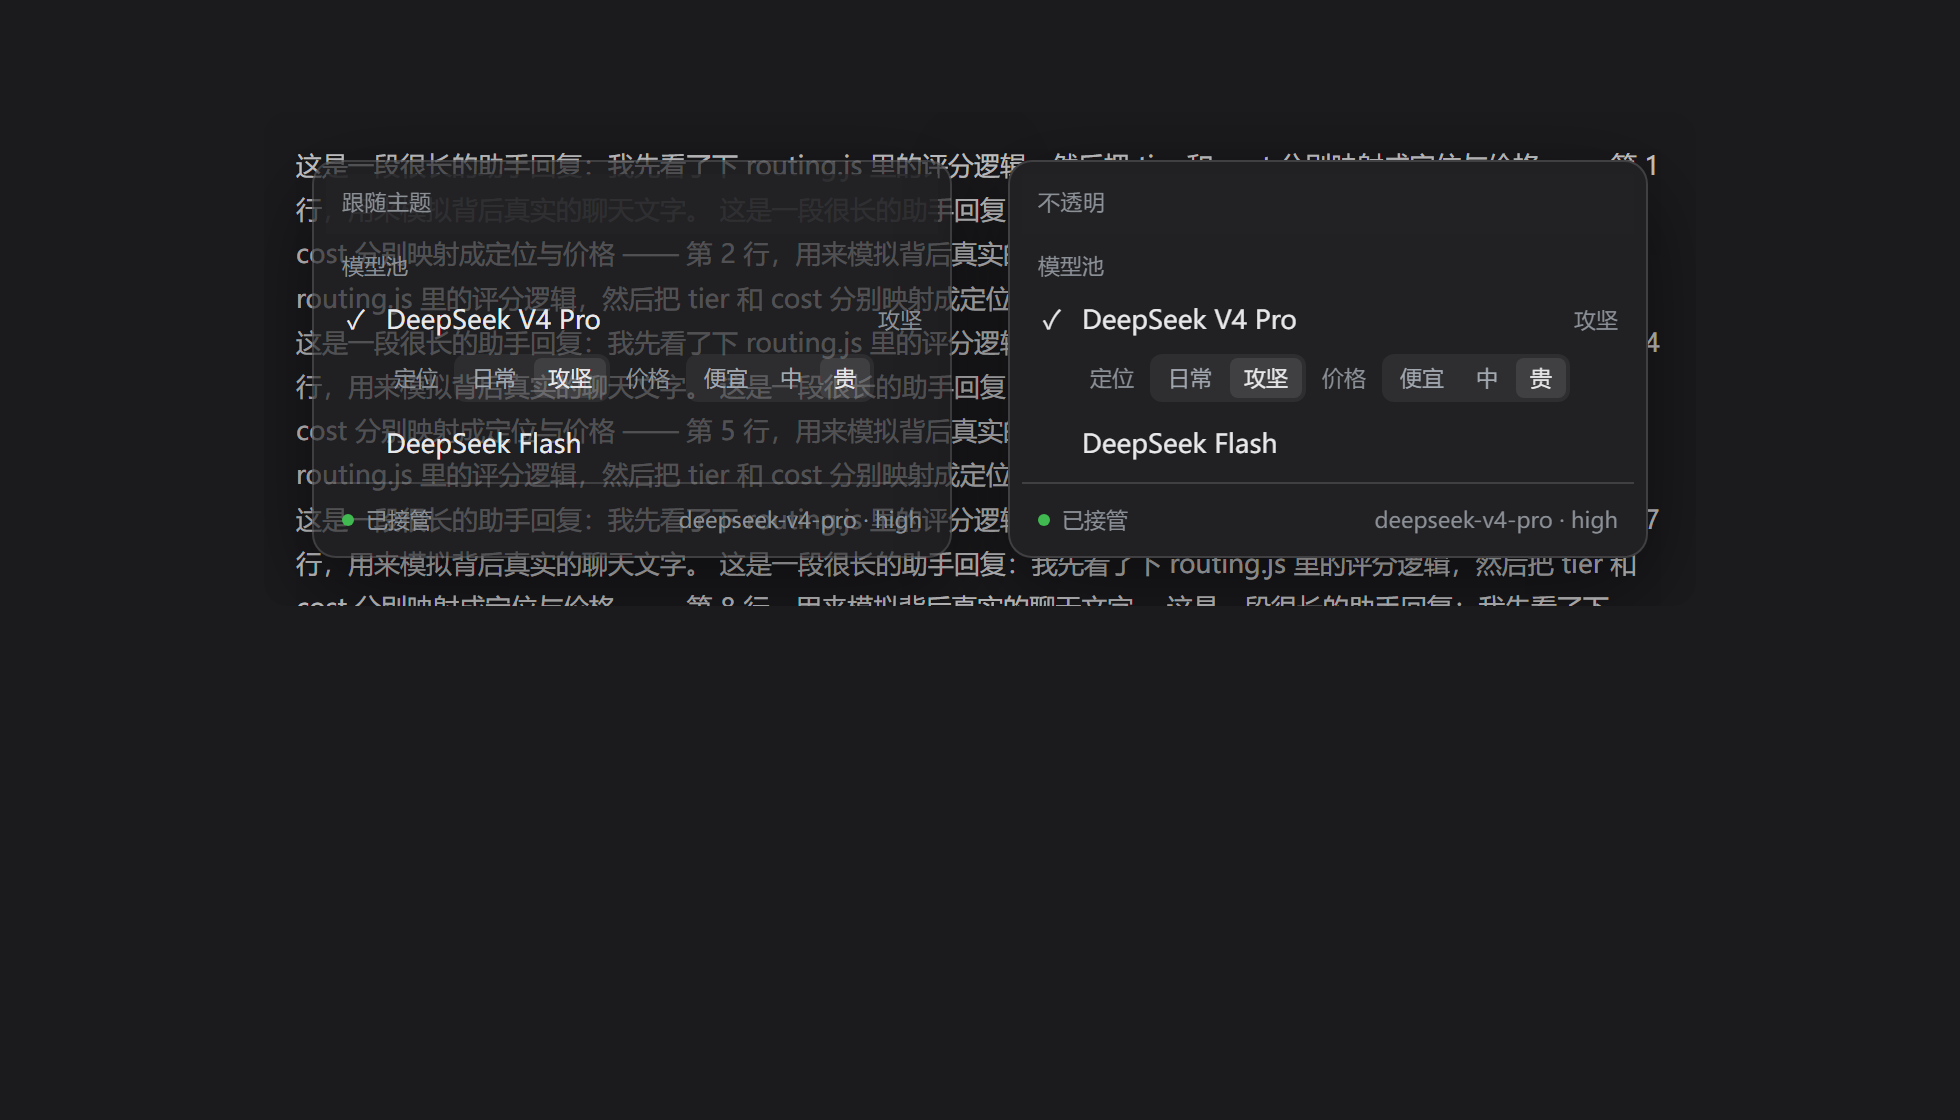
The router control is the composer model cell (v0.11.0)
The router's control registers into the shipped conversation.input.model seat at priority -1,
below the shipped ModelSelect (priority 0, from @deepseek-ai/dsh-client-ui-model-selection). The
slots engine renders the lowest priority, so the router's merged control takes over the composer model
cell and the composer shows a single control instead of a second chip beside the official picker.
That one control keeps both halves. The official half is 本会话模型 / Session model and 推理等级 /
Reasoning effort, driven by the real ModelDirectory through props.directory.store subscribe,
props.load() and props.select({ provider, model, reasoningEffort }): provider/model groups, the
current row's check, the pending spinner, the provider-default row, catalog loading / error / retry, and
the official "model · effort" trigger label. Below it sit the router's own groups: the 接管 status,
控制范围 (模型+思考 / 思考 / 模型) and 任务类型, then the model list itself — the pool is folded into the
model rows: every session-model row carries a 模型池 / Model pool chip on its right, tapping it pools or
unpools that model, a pooled row expands its 定位 / 价格 / 视觉 controls underneath, and pool entries
whose provider group is not in the directory gather under 其他模型 / Other models with the manual
"type a model id" row. Then 任务预设 and 更多. Every mutation goes to the host over same-origin
/model-router/* routes, and the per-call route row in the conversation is unchanged.
The old conversation.input.right chip (model-router:composer-control, order 20) is still registered,
but it self-retracts — it disposes itself as soon as the seat registration lands — so a normal host
renders an empty .right column and only ever sees the merged cell. A host that rejects or renames the
seat keeps the chip as its fallback.
0.10.0 tried this first and was rolled back in 0.10.1: the seat rendered blank and a restart failed to
boot. The root cause: cordis resolves nested services such as remote.session by walking fibers
upward from the calling fiber, so the client plugin itself must declare sessions, remote and
remote.session before a method may touch ModelDirectory.directoryFor(). The plugin-level inject is
now ["slots", "uiConversation", "sessions", "remote", "remote.session"].
Limits. This is a registration into the shipped seat, not a patch of the official component: the
official popup's internals (portal menu, search box, keyboard navigation, module CSS) are not
replicated, only its selection semantics. A DSH that stops declaring conversation.input.model makes
the seat registration fail silently and the small fallback chip takes over. Plugin source changes still
need a full dsh web/desktop restart.
The panel matches the host (v0.6.4)
The composer control is styled with the harness's own tokens — the same 34px rows,
hover wash, glyph checks, segmented controls and popover elevation the built-in
menus use. Open docs/ui-preview.html in a browser (or see
docs/preview-dark.png / docs/preview-light.png)
to look at it without installing anything.


Everything is a click (v0.6.2)
The composer control is the whole configuration surface — no JSON or YAML:
| Section | What you do |
|---|---|
| mode | click 模型+思考 / 思考 / 模型; in 思考, pick the one model the router may tune; a manual pick adds a resume button |
| task type | pick auto (keyword rules) or one of your presets |
| model pool | tick models from the live catalog, then set tier / cost / vision with dropdowns |
| task presets | + 新建预设 → click a keyword pack (写作 / 代码 / 翻译 / 分析) or add a word → choose each pooled model's weight |
| more | image steps, task detection (rules / semantic), context pressure |
Everything persists in <profile>/.model-router/state.json through the same-origin
/model-router/* routes, so the profile row config stays optional.
Every call shows its route (v0.8.0)
Every tool call in the conversation now carries one compact line with the model and thinking level that actually ran that segment:
deepseek-official/deepseek-v4-pro · high
The host folds the session's own events into the modelRouterRoute session projection
(stateVersion 1): request/header gives the provider, model and effort in force, step/start
gives the turn and step, and tool/call records that pair under the call id. The effort is null
when the adapter owns the default, and those rows show the localized 默认 / default label.
The projection keeps the last 200 calls per session and drops the oldest.
The client half registers a model-router-route conversation Definition on every tool/call and
renders the row through the conversation.chat.node slot, anchored right after the call (+0.1).
It reads the projection defensively: a call id the host has not folded yet renders nothing rather
than borrowing another call's route. The line is a separate compact row next to the tool call —
see Limitations for why it is not a badge inside the tool row.
Images, session signals, subagents and the classifier (v0.6.0)
Images. imagePolicy: vision sends a task that carries an image to a vision model: the pool
entry tagged vision, or visionModel when set explicitly. The image is task-scoped — the next
command without one goes back to the normal tier.
Session signals. The router reads core session projections and lets them sharpen the choice:
| Signal | Effect |
|---|---|
active todo (todos) |
feeds task-type matching — a todo list states the work better than the prompt |
| context pressure | above signals.contextPressure (0–1) the cheap tier is preferred |
| token total | above signals.sessionTokens (0 = off) the cheap tier is preferred |
delegationDepth |
subagents prefer the cheap tier (subagent.preferCheap) |
Every decision records the signals it saw, so /router and the composer control can explain it.
/router prints the scope, engagement, pool, task type, the recent decisions and the task's
strong-tier spend.
Classifier. classifier: llm makes one small call per turn to pick a preset
(classifierModel, effort off, classifierTimeoutMs), caches it for the turn and falls back to the
keyword rules on any failure. The default stays rules.
The five rules
- No ratchet. Turn depth contributes no score by default (
scoring.turnPerPoint: 0) and tool calls are counted per task, so a long agent run does not drift toward the most expensive effort. A long run is not a harder task. Since 0.9.0 a tool loop is a score signal only — it no longer pins the class atengineering(scoring.toolCallClass). - Escalation needs evidence. Inside the current task,
escalateOnErrorsfailing tool results, or the same tool call retried with identical argumentsescalateOnRepeatstimes, step the class up — at mostmaxEscalationstimes. Nothing else moves it. maxis opt-in. Automatic routing never emitsmaxunlessallowMaxis set. The ceiling is enforced at the effort level, so even a hand-written route table asking formaxis clamped.- A manually selected
maxis demoted too (demoteManualMax), but only for models this plugin manages. Other models are left alone. EnablingallowMaxturns both clamps off. - Thinking stays on.
offis not an automatic route. DeepSeek's Messages API rejects a thinking-enabled request whose history contains an assistant tool call produced while thinking was disabled (The content[].thinking in the thinking mode must be passed back to the API). A cheap step can still call a tool, and the next step of the same task is an engineering tool loop, so oneoffstep followed by ahighstep failed the turn.trivialnow routes tolow, and any configured or manually selectedoffis raised tolowunlessallowThinkingOffis set. Recovery: if a conversation already contains such a turn (from an earlier version, or from a hand-selectedoff), the router detects it and keeps that session atoffinstead of failing every step, and logs one warning. Compact the session or start a new one to get thinking back.
Task boundaries come from agent/inbox/claimed, which is what actually opens a new piece of work.
When a task ends on an unresolved failure, the next one inherits a single hesitant step up — and only
if it is engineering or hard work. A one-line "translate this" never inherits a crash.
Tool loops no longer pin the effort at high (v0.9.0)
Before 0.9.0, classifyStep classified a step as engineering whenever its task had already seen one
tool call (cue agent tool loop), and engineering routes to high. Because the per-task tool
counter only resets when a new command is claimed, every step from the first tool call to the end of the
Agent run stayed at high. There was no way back down mid-loop: trivial needs a cheap cue and at
most 60 tokens, and standard required zero tool calls. And with allowMax: false (the default),
max is demoted to high, so hard and engineering applied the same effort — evidence
escalation changed nothing for a task that was already engineering.
Measured before: 帮我把这个文件里的日志改成中文 ran standard/low at 0 tools, then
engineering/high at 1, 3, 6, 12 and 25 tools for the rest of the task; 翻译一下这句话 with one
tool also went to high.
scoring.toolCallClass (default standard) decides whether a tool loop can earn the engineering class
on its own. With standard, tool activity still adds score (toolCallBase = 5, toolCallAt = 3,
toolCallBig = 8) but the brief — strong cues or structural text — decides the class, and
escalateOnErrors / escalateOnRepeats still escalate on evidence. Set it to engineering to
restore the old rule; any other value falls back to standard. Measured after: a casual brief with
tools stays standard/low throughout, an engineering brief stays engineering/high throughout.
hard still collapses to high unless allowMax: true, and routes.<class>.effort (for example
routes.engineering.effort: low) is the direct way to say how expensive a class may get.
Configuration
The plugin reads its config from its row in the profile's cordis.patch.yml:
- id: model-router
  config:
    mode: auto            # auto | off
    model: deepseek-flash
    allowMax: false       # true enables max for auto routing and manual selection alike
    maxFallback: high     # where max collapses when allowMax is false
    allowThinkingOff: false # true re-enables effort "off" (see rule 5: it breaks tool loops)
    control: full         # full | effort | model — what the router may choose
    manualOverride:
      yieldOnManual: true        # a manual pick stands; routing stands down
      resumeOnNextCommand: true  # …and re-engages on your next command
    pool: []              # whitelist; empty keeps the single `model` above
    presets: {}           # task type -> { match: [...], weights: { modelId: 0-100 } }
    scoring:
      costPenalty: 0.4    # how strongly relative cost subtracts from a pool score
      turnPerPoint: 0     # raise this to let long sessions weigh more (not recommended)
      toolCallClass: standard  # class a tool loop earns: standard (0.9.0) | engineering (pre-0.9.0)
    hysteresis:
      downAfter: 2        # quiet steps required before the effort steps down
    imagePolicy: keep     # keep | vision — route image tasks to a vision model
    visionModel: null     # explicit vision model; the pool's `vision` tag is used otherwise
    signals:
      todos: true         # let the active todo feed task-type matching
      contextPressure: 0.75  # above this occupancy, prefer the cheap tier (0 disables)
      sessionTokens: 0    # above this token total, prefer the cheap tier (0 disables)
    subagent:
      preferCheap: true   # delegated work stays cheap unless a preset says otherwise
    classifier: rules     # rules | llm — llm makes one small call per turn
    classifierModel: null # model used by the llm classifier (defaults to the first pool entry)
    escalateOnErrors: 2   # failed tool results needed to step up
    escalateOnRepeats: 3  # identical retries needed to step up
    routes:
      trivial:     { effort: low }   # "off" here is raised to low unless allowThinkingOff
      standard:    { effort: low }
      engineering: { effort: high }
      hard:        { effort: max }
DSH_MODEL_ROUTER=off|auto overrides mode at boot.
| Key | Default | Meaning |
|---|---|---|
mode |
auto |
off passes every request through, except the manual-max clamp |
provider |
deepseek-official |
only this provider is ever touched |
model |
deepseek-flash |
the one model this plugin drives |
familyPattern |
^deepseek-(flash|v4) |
conversation models it may take over; a pro session is pulled back to flash |
allowMax |
false |
whether max is reachable at all |
maxFallback |
high |
what max collapses to |
demoteManualMax |
true |
also demote a manually selected max |
allowThinkingOff |
false |
allow effort off again; only for sessions that stay non-thinking |
control |
full |
what the router owns: full, effort or model |
manualOverride.yieldOnManual |
true |
a manual pick in the scope that owns it makes the router stand down |
manualOverride.resumeOnNextCommand |
true |
the next command re-engages it |
pool |
[] |
provider/model whitelist with cost/tier/tags/weights/maxPerTask |
presets |
{} |
task types with match rules and per-model weights |
scoring.costPenalty |
0.4 |
relative-cost weight in the pool score |
scoring.toolCallClass |
standard |
class a tool loop earns on its own: standard (0.9.0) or engineering (pre-0.9.0 rule); any other value falls back to standard |
hysteresis.downAfter |
2 |
quiet steps before a downgrade applies |
classifier |
rules |
rules or llm (one small call per turn, rules as fallback) |
classifierModel |
first pool entry | model the LLM classifier uses |
imagePolicy |
keep |
vision routes a task carrying an image to a vision model |
visionModel |
null |
explicit vision model id |
signals.todos |
true |
let the active todo feed task-type matching |
signals.contextPressure |
0.75 |
occupancy above which the cheap tier is preferred |
signals.sessionTokens |
0 |
token total above which the cheap tier is preferred |
subagent.preferCheap |
true |
delegated work prefers the cheap tier |
leaveImageSteps |
true |
steps carrying images keep the caller's model |
imagePolicy |
keep |
set to flash to route image steps too (the flash model has native vision) |
escalateOnErrors |
2 |
failure-evidence threshold |
escalateOnRepeats |
3 |
repeated-call threshold |
maxEscalations |
2 |
most classes a single task may climb |
carryUnresolved |
true |
carry one step up from an unresolved failure |
Install
dsh plugin is a pnpm forwarder, so any pnpm specifier works. From the npm registry:
dsh plugin --profile web add @neptune810/dsh-model-router
or straight from the repository:
dsh plugin --profile web add github:Neptune810/dsh-model-router
Restart dsh web afterwards. Because the router registers listeners at boot, a reload is not
enough.
Requirements
- Node 20 or newer.
- Verified against
@deepseek-ai/dsh0.1.7-rc.2. The plugin usesagent/request,agent/inbox/claimed, andsession.deriveMessages(). Noengines.dshrange is declared, so the plugin market keeps this entry visible rather than guessing it incompatible.
Limitations
- No config schema. Settings are read from the profile patch layer shown above and do not render
as a form in the settings UI. This is deliberate: a schema would require importing
@deepseek-ai/*packages, which a plugin installed beside the profile cannot resolve. - The router only touches the
deepseek-officialprovider and models matchingfamilyPattern. - The router control takes over the official model cell by registration, not by patching the
component. It registers into
conversation.input.modelat priority -1 (below the shippedModelSelectat 0), keeping the official model + effort sections inside its own panel. The oldconversation.input.rightchip (model-router:composer-control, order 20) self-retracts and is only a fallback for a host that rejects the seat. 0.10.0's first attempt shipped a blank cell and was rolled back in 0.10.1 because it had not declaredsessions/remote/remote.sessionon the plugin root. - The per-call route line is a separate small row anchored after the tool call, not a badge inside
the harness's own tool row or inside the thinking chain: a keyed slot replaces whatever it targets,
and the thinking chain exposes no child slot. A call the host has not folded yet shows nothing
rather than guessing. Plugin source changes only appear after you restart
dsh web.
Tests
node --test
131 tests. test/policy.test.js (34) covers classification, the absence of a ratchet, the
unreachable max, the refusal of off, evidence escalation, effort clamping, the poisoned-history
detector, tool-result error parsing, and the toolCallClass knob (default standard, engineering
restores the pre-0.9.0 rule, any other value coerces to standard); test/routing.test.js (12) covers the pool, preset
weights, vision filtering, maxPerTask, effort-vocabulary mapping and hysteresis;
test/plugin.test.js (16) drives the host wiring with ctx/agent doubles, including a quiet tool loop
that stays at its brief's class instead of climbing to high; test/modes.test.js (21)
covers the three scopes, manual yield + resume, same-origin route guards (including a request whose Origin the
Desktop proxy stripped, and one carrying Origin: null), pool/preset editing, a
pinned task type, a third-party effort vocabulary, vision routing, subagent frugality, todo-driven
task types, context pressure, the /router command and the LLM classifier;
test/effort-model.test.js (10) covers effort scope bound to one model (unbound stands off, binding
clears the pending flag, only the bound model's effort moves, the vocabulary comes from its own pool
entry, a session-less binding becomes the default) and the scope-aware manual yield (a model switch in
effort scope is not an override, an effort change is, model scope ignores effort, full scope reacts to
both) plus the route's clearing and validation; test/route-projection.test.js (12) covers the
projection contract (key/stateVersion, plain-JSON state, header folding with absent vs explicit null
effort, turn/step tracking, the header in force at a call, the fallback to the call's own values,
repeated call ids, the 200-entry cap in insertion order, integer-like call-id ordering, purity and a
JSON round-trip) plus the host registration and a host without the service; test/client.test.js (26)
loads the shipped browser bundle in a VM and asserts the registration (the route row, the composer chip
as a self-retracting fallback, and the merged seat on conversation.input.model at priority -1), the
closed trigger, the documented host routes, the route
Definition's match/anchor and its defensive read of the folded projection, the localized default label,
the seat face delegating to the session directory, the official selection semantics (model rows without
reasoningEffort, effort rows with it, the provider default, the current-row no-op, a locked session, an
unavailable subagent cell, a failed pick keeping its message, catalog errors offering a retry, and group
order), the router half's control/pool/settings payloads and the /effort-model binding, the pool
control that collapses the list and reopens it, and the declared ui-chat seat and uiConversation
service.
License
MIT
Comments
Comments live in GitHub Discussions. Sign in with GitHub to post or react.